
Ruby on Rails caching in 2026 is no longer a simple performance nicety — it is a first-class architectural concern that determines whether a Rails 8 application can serve millions of requests per day on modest infrastructure. The framework has evolved substantially since the early days of page caching gems, and modern Rails ships with a mature, layered caching stack built around ActiveSupport::Cache, Solid Cache, and cache versioning primitives that make correctness far easier to reason about. This guide walks through the complete Rails caching toolkit as it exists today, from fragment and Russian doll caching through low-level fetch patterns, cache store selection, and the observability practices that separate production-grade systems from fragile ones.
What follows is a deeply technical, opinionated tour of Rails caching written for engineers who already know their way around controllers, views, and Active Record. We will cover the mechanics of cache keys, the subtle invalidation semantics that trip up even senior developers, the trade-offs between Redis, Memcached, Solid Cache, and in-memory stores, and the concrete patterns that scale. Along the way we will look at real code, benchmark-style comparisons, and the failure modes that cause stale data bugs in production. By the end you should be able to design a caching layer that is fast, correct, and observable — and to know exactly when caching is the wrong answer.
Why Rails Caching Strategy Matters More Than Ever in 2026
The economics of web performance have shifted dramatically. Database round-trips that cost microseconds on a local Postgres instance become tens of milliseconds across an availability zone, and a single unoptimised N+1 query in a hot view can multiply into hundreds of milliseconds of latency under load. Rails caching exists to collapse those repeated costs into a single computation, and in 2026 the framework gives you more control over that collapse than at any point in its history. The introduction of Solid Cache as a default-friendly store, the maturation of cache versioning, and the widespread adoption of HTTP-level caching via ETags and stale-while-revalidate have all changed what a well-architected Rails app looks like.
It is tempting to treat caching as a bolt-on optimisation you add after profiling reveals a bottleneck. That approach works for small applications, but it breaks down at scale because caching decisions are deeply entangled with data modelling, invalidation semantics, and deployment topology. A cache key that includes a timestamp is only correct if every write path touches that timestamp; a fragment cache is only safe if the underlying partial has no hidden dependencies on request-scoped state. Understanding these couplings before you write the first cache call saves weeks of debugging stale-data incidents later.
The performance ceiling of an uncached Rails application is largely determined by your database. Even with connection pooling, prepared statements, and a well-tuned Postgres, a request that issues fifty queries will spend most of its wall-clock time waiting on the database. Caching attacks this directly by eliminating queries entirely for repeat requests. In practice, teams that adopt disciplined fragment caching routinely see p95 latency drop by 60 to 80 percent on read-heavy pages, and database CPU utilisation fall by similar margins. Those numbers are not marketing — they are the predictable result of removing redundant work.
There is also a correctness dimension that is easy to overlook. Caching is fundamentally a distributed state problem: you are storing a copy of data somewhere other than its source of truth, and you must guarantee that the copy is either fresh or provably stale in a way your application tolerates. Rails gives you tools for this — cache versioning, touch cascades, expiry windows — but it cannot make the decision for you. The engineer who understands invalidation semantics will build systems that are both fast and correct; the engineer who treats caching as magic will ship bugs that only appear under specific write patterns.
Finally, the tooling landscape has matured. Observability platforms now expose cache hit ratios as first-class metrics, Rails ships with ActiveSupport::Notifications hooks for cache operations, and Solid Cache stores cache entries in your existing database so you no longer need a separate Redis cluster for modest workloads. That last change is significant: it means a small team can adopt production-grade caching without adding operational surface area. The rest of this guide assumes you want to exploit that maturity fully.
The Rails Caching Stack: Layers, Stores, and Abstractions
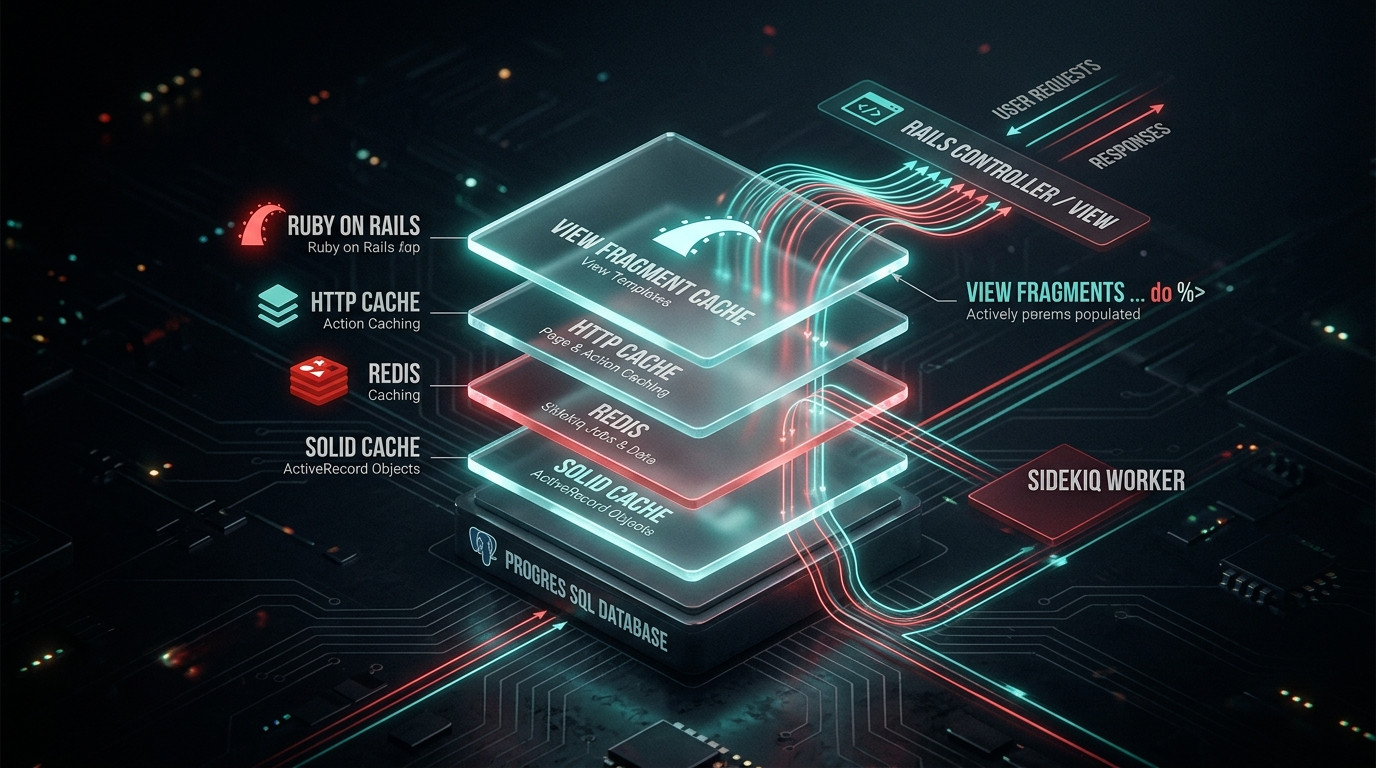
Rails caching is not a single feature but a stack of cooperating layers, each operating at a different granularity. At the top you have HTTP caching, where responses carry Cache-Control, ETag, and Last-Modified headers that let browsers and CDNs serve content without touching your application at all. Below that sits action-level caching, where entire controller responses are memoised. Further down are fragment caching and Russian doll caching, which operate on pieces of rendered views. At the bottom is low-level caching, where you store arbitrary computed values keyed by strings you control. Understanding which layer to reach for is the single most important skill in Rails caching.
Every layer above the HTTP level ultimately talks to a cache store through the ActiveSupport::Cache::Store interface. That interface exposes a small, consistent API — read, write, fetch, delete, exist?, and increment/decrement — regardless of whether the backing store is Redis, Memcached, a file directory, or a database table. This abstraction is what lets you swap stores between environments without rewriting application code, and it is why Rails caching advice tends to be store-agnostic. The store you choose affects performance, durability, and operational cost, but not the shape of your caching calls.
Cache keys are the connective tissue of the entire stack. When you call cache(product) in a view, Rails derives a key from the object’s class name, its id, and its updatedat timestamp, producing something like products/42-20260115123045. That timestamp is the invalidation mechanism: when the record is updated, updatedat changes, the key changes, and the old entry becomes unreachable. This design is elegant because it requires no explicit invalidation logic, but it depends entirely on the timestamp being accurate and on every write path touching the record. If you update a product via updatecolumn, which skips callbacks and does not touch updatedat, you will serve stale fragments indefinitely.
Rails 8 also supports cache versioning, a mechanism that lets you invalidate an entire class of cache entries by bumping a version number rather than waiting for timestamps to change. This is invaluable during deployments that change view markup, because a markup change without a corresponding data change would otherwise leave stale HTML in the cache. Versioning is configured per-model and per-view-helper, and it composes cleanly with timestamp-based keys. The combination gives you both fine-grained invalidation (timestamps) and coarse-grained invalidation (versions).
| Layer | Granularity | Typical Store | Invalidation Trigger |
|---|---|---|---|
| HTTP caching | Full response | Browser / CDN | ETag, Last-Modified, max-age |
| Action caching | Controller action | Redis / Solid Cache | Action-level key + expiry |
| Fragment caching | View fragment | Redis / Solid Cache | Record updated_at |
| Russian doll caching | Nested fragments | Redis / Solid Cache | Parent touch cascade |
| Low-level caching | Arbitrary value | Any store | Manual key + expiry |
Choosing a layer is a trade-off between hit rate and invalidation complexity. HTTP caching gives the highest hit rate because it bypasses your servers entirely, but it is only safe for content that is identical for all users or that varies only by URL. Fragment caching gives a lower hit rate but works for personalised pages. Low-level caching gives the most control but requires you to manage keys and expiry yourself. Most production applications use all three simultaneously, with HTTP caching for public pages, fragment caching for authenticated views, and low-level caching for expensive computations.
Fragment Caching in Depth: Keys, Expiry, and Partial Rendering
Fragment caching is the workhorse of Rails view performance. The idea is simple: wrap a portion of a view in a cache block, and Rails will render it once, store the resulting HTML in the cache store, and serve the stored HTML on subsequent requests until the cache key changes. The performance win comes from skipping the rendering work entirely — no partial lookups, no helper calls, no database queries inside the fragment. On a page that renders fifty product cards, caching each card individually can reduce render time from hundreds of milliseconds to single digits.
The cache helper is the entry point. In its simplest form you pass it an object, and Rails derives the key from that object. For a collection of products, you iterate and cache each one. The generated key includes the model name, the record id, and the updated_at timestamp, so any update to a product automatically produces a new key and a fresh render. This is the mechanism that makes fragment caching safe without explicit invalidation: the cache is keyed by the data itself, and the data’s timestamp is the version.
<%# app/views/products/index.html.erb %>
<h1>Products</h1>

<div class="product-grid">
  <% @products.each do |product| %>
    <% cache product do %>
      <%= render partial: 'product', locals: { product: product } %>
    <% end %>
  <% end %>
</div>
You can customise the key by passing an array, which Rails joins into a composite key. This is useful when a fragment depends on more than one record, or when it depends on a value that is not a record at all. For example, caching a product card that also displays the current user’s favourite status would need a key that includes both the product and the user. Passing [product, current_user] produces a key like products/42-20260115123045-users/7-20260110100000, and the fragment is invalidated when either record changes.
<% @products.each do |product| %>
  <% cache [product, current_user] do %>
    <%= render partial: 'product', locals: { product: product, user: current_user } %>
  <% end %>
<% end %>
Expiry is the other lever. By default, fragment caches live until their key changes or the store evicts them under memory pressure. You can pass an expiresin option to bound their lifetime, which is useful for fragments that depend on data outside your control — a third-party API response, a time-sensitive promotion, or a value that changes without touching a timestamp. Setting expiresin: 15.minutes means the fragment is guaranteed to be re-rendered at least every fifteen minutes, which caps the staleness window even if invalidation logic has a bug.
A common pitfall is caching a fragment that depends on request-scoped state without including that state in the key. If a partial renders differently for admins and regular users, and you cache it with just the record as the key, the first user to hit the page determines what everyone sees. The fix is to include the varying state in the key — cache [product, current_user.role] or similar. This is the single most frequent source of caching bugs in Rails applications, and it is worth auditing every cache call for hidden dependencies before shipping.
Russian Doll Caching and the Touch Cascade Pattern
Russian doll caching extends fragment caching to nested structures. The name comes from the way the caches nest: an outer fragment contains inner fragments, each cached independently, so that a change to an inner fragment invalidates only that fragment while the outer fragment can be reused if its own key has not changed. This is enormously efficient for hierarchical data — categories containing subcategories containing products — because a change to one product does not force a re-render of the entire category tree.
The mechanism relies on the outer fragment’s key changing when any inner fragment changes. Rails achieves this through the touch cascade: when a child record is updated, it touches its parent, which updates the parent’s updatedat timestamp, which changes the parent’s cache key, which invalidates the parent fragment. For this to work, you must declare the relationship with touches: true on the belongsto association. Without it, updating a product will not invalidate the category fragment that contains it, and you will serve stale category pages.
# app/models/product.rb
class Product < ApplicationRecord
  belongs_to :subcategory, touch: true
end

# app/models/subcategory.rb
class Subcategory < ApplicationRecord
  belongs_to :category, touch: true
  has_many :products, dependent: :destroy
end

# app/models/category.rb
class Category < ApplicationRecord
  has_many :subcategories, dependent: :destroy
  has_many :products, through: :subcategories
end
With the cascade in place, the view code nests cache blocks naturally. The outer cache wraps the category, the middle cache wraps each subcategory, and the inner cache wraps each product. When a product is updated, its own fragment is invalidated by its timestamp, its subcategory is invalidated by the touch cascade, and its category is invalidated by the next level of the cascade. The result is that only the affected path through the tree is re-rendered, while sibling branches remain cached.
<% @categories.each do |category| %>
  <% cache category do %>
    <h2><%= category.name %></h2>
    <% category.subcategories.each do |subcategory| %>
      <% cache subcategory do %>
        <h3><%= subcategory.name %></h3>
        <% subcategory.products.each do |product| %>
          <% cache product do %>
            <%= render partial: 'product', locals: { product: product } %>
          <% end %>
        <% end %>
      <% end %>
    <% end %>
  <% end %>
<% end %>
The trade-off is write amplification. Every product update now triggers an update to its subcategory and its category, which means three database writes instead of one. For read-heavy workloads this is an excellent trade, because the cost of a write is paid once while the benefit of a cache hit is realised on every subsequent read. For write-heavy workloads, however, the cascade can become a bottleneck, and you may need to batch touches or move to a different invalidation strategy such as cache versioning.
Cache versioning offers an alternative to the touch cascade for coarse-grained invalidation. Instead of touching parents on every write, you bump a version number stored in a shared location — a Redis key, a database row, or a Rails.cache entry — and include that version in the cache key. When the version changes, all fragments keyed with the old version become unreachable. This is cheaper on writes but invalidates more than necessary, so it is best reserved for cases where the cascade is too expensive or where the invalidation boundary is naturally coarse.
Low-Level Caching with fetch, write, and Cache Dependency Management
Not everything worth caching is a view fragment. Expensive computations — aggregations, external API responses, machine learning inference results — belong in low-level caches, where you control the key and the expiry directly. The fetch method is the primary tool: it reads from the cache, and if the key is missing, executes the block, stores the result, and returns it. This read-through pattern is the cleanest way to memoise expensive work across requests.
# app/models/product.rb
class Product < ApplicationRecord
  def self.average_price
    Rails.cache.fetch('products/average_price', expires_in: 10.minutes) do
      where(active: true).average(:price).to_f
    end
  end
end
The key you choose is entirely your responsibility, which is both the power and the danger of low-level caching. A key like products/averageprice is fine for a global aggregate, but if the value varies by tenant, region, or user, the key must encode that variation. A common pattern is to build keys from a namespace plus the varying dimensions, for example products/averageprice/tenant-42/region-eu. Failing to include a dimension means one tenant sees another tenant’s data, which is both a correctness bug and a security incident.
Invalidation in low-level caching is manual. You can delete a key with Rails.cache.delete, or overwrite it with Rails.cache.write using the force option. The fetch method also accepts a force option that bypasses the read and always executes the block, which is useful in tests or after a known data migration. For values that change on a predictable schedule, expires_in is usually sufficient and far simpler than explicit invalidation. For values that change unpredictably, you need a write path that deletes or overwrites the key whenever the underlying data changes.
# Invalidate the cached average whenever a product is saved
class Product < ApplicationRecord
  after_commit :expire_average_price_cache

  private

  def expire_average_price_cache
    Rails.cache.delete('products/average_price')
  end
end
A subtle but important detail is that fetch is not atomic across processes. Two concurrent requests that both miss the cache will both execute the block and both write the result, a phenomenon known as a cache stampede or thundering herd. For cheap blocks this is harmless, but for expensive blocks it can overwhelm your database. Rails 8 does not provide built-in stampede protection, so production systems typically add a short-lived lock — a Redis SET NX with expiry, or a database advisory lock — around the expensive computation. Alternatively, you can use probabilistic early expiration, where a fraction of requests refresh the cache before it expires, smoothing the load.
Choosing a Cache Store: Redis, Memcached, Solid Cache, and Memory
The cache store is the backend that actually holds your cached data. Rails ships with several built-in stores and supports community stores for Redis and Memcached. The choice affects latency, durability, eviction behaviour, and operational complexity, and it is one of the few caching decisions that is genuinely environment-specific. A development machine can use the memory store; a production cluster serving millions of requests needs something more robust.
| Store | Latency | Durability | Shared Across Processes | Best For |
|---|---|---|---|---|
| MemoryStore | Fastest | None | No | Development, tests, single-process |
| FileStore | Slow | Disk | Yes (shared FS) | Small deployments, no external deps |
| MemCacheStore | Very fast | None | Yes | High-throughput, ephemeral caches |
| RedisCacheStore | Very fast | Optional | Yes | General production use, persistence |
| SolidCacheStore | Fast | Database | Yes | Teams avoiding extra infrastructure |
The memory store keeps everything in the process, which makes it the fastest option but also the least useful in production because each Puma worker has its own cache. A request served by worker A will not see a cache entry written by worker B, so hit rates are unpredictable and invalidation is impossible across workers. Use it in development and tests, where its speed and zero-configuration nature are ideal, but never in a multi-process production deployment.
Redis has become the de facto standard for Rails caching in production. It offers sub-millisecond latency, optional persistence, atomic operations that support stampede protection, and a rich set of data structures that go beyond simple key-value storage. The RedisCacheStore in Rails 8 supports connection pooling, failover to a secondary Redis, and error handling that degrades gracefully when Redis is unavailable. For most teams, Redis is the right default: it is well understood, widely available as a managed service, and its operational characteristics are predictable.
Solid Cache is the newer entrant and deserves serious consideration. It stores cache entries in your existing relational database, using a dedicated table with an efficient schema and a built-in eviction policy based on max-age and max-entries. The appeal is operational simplicity: no separate Redis cluster, no additional failure domain, and cache data benefits from your existing database backups and replication. The trade-off is latency — a database round-trip is slower than a Redis round-trip — but for applications where cache reads are already dominated by network latency, the difference is often negligible. Solid Cache is an excellent choice for teams that value simplicity over raw speed.
Memcached remains a viable option for pure ephemeral caching. It is simpler than Redis, has no persistence, and is extremely fast for simple get/set workloads. Its limitation is the absence of advanced features: no atomic compare-and-swap, no pub/sub, no data structures beyond strings. If your caching needs are simple and you already run Memcached, it will serve you well. If you need stampede protection or cache versioning backed by atomic operations, Redis is the better fit. Whichever store you choose, configure it explicitly in each environment and verify that Rails.cache points to the right backend before deploying.
Cache Expiry, Eviction, and Stampede Protection Strategies
Expiry and eviction are distinct concepts that are often conflated. Expiry is a policy you set: a cache entry with expires_in: 5.minutes is logically invalid after five minutes, regardless of whether the store has room for it. Eviction is a policy the store applies: when memory or disk fills up, the store discards entries according to its own rules, typically least-recently-used. A cache entry can be evicted long before it expires, and it can expire long before it is evicted. Understanding both is essential for predicting cache behaviour under load.
Setting expiry correctly is a balancing act. Too short, and you re-compute expensive values constantly, defeating the purpose of caching. Too long, and you serve stale data for an unacceptable window. The right value depends on how much staleness your application tolerates and how expensive the computation is. A good heuristic is to set expiry to the longest window during which stale data is acceptable, then rely on explicit invalidation to shorten it when data actually changes. Expiry is a safety net; invalidation is the primary mechanism.
Eviction is governed by the store. Redis, for example, supports several eviction policies: noeviction returns errors when memory is full, allkeys-lru evicts the least-recently-used key across the entire dataset, and volatile-lru evicts only keys with a TTL set. For a cache-only Redis instance, allkeys-lru is usually the right choice because it maximises hit rate under memory pressure. If you share a Redis instance between caching and other workloads, volatile-lru lets you protect non-cache keys from eviction. Configuring the wrong policy can cause either cache misses or, worse, data loss in a shared instance.
Stampede protection is the practice of preventing many concurrent requests from simultaneously recomputing an expired value. The classic scenario: a popular cache key expires, a thousand requests arrive in the same millisecond, all miss the cache, and all execute the expensive block. The database receives a thousand identical queries and collapses. There are several mitigations. A distributed lock ensures only one request recomputes while others wait or serve stale data. Probabilistic early expiration refreshes the cache slightly before it expires, spreading the refresh across many requests. Stale-while-revalidate serves the stale value immediately and refreshes in the background.
# Probabilistic early expiration for a hot cache key
def fetch_with_early_expiration(key, ttl:, beta: 1.0)
  entry = Rails.cache.read(key)
  if entry
    age = Time.current - entry[:stored_at]
    # Refresh early with probability that increases as the entry ages
    if age > ttl * (1 - beta * Math.log(rand))
      return entry[:value]
    end
  end

  value = yield
  Rails.cache.write(key, { value: value, stored_at: Time.current }, expires_in: ttl)
  value
end
Rails 8 does not ship stampede protection out of the box, so teams implement it themselves or adopt a gem. The important thing is to recognise the pattern and decide deliberately whether your workload needs it. A cache key that is read once per hour will never stampede; a cache key that is read ten thousand times per second absolutely will. Profiling your cache hit patterns and identifying hot keys is the first step toward protecting them.
Observability: Measuring Hit Rates, Latency, and Cache Health
A caching layer you cannot measure is a caching layer you cannot trust. The first metric to instrument is the hit rate: the fraction of cache reads that return a value. A hit rate below 80 percent on a fragment cache usually indicates a key that changes too often, a TTL that is too short, or an eviction policy that is discarding entries prematurely. A hit rate above 99 percent on a low-level cache can indicate a key that never changes and therefore never refreshes, which is a staleness risk rather than a success.
Rails exposes cache operations through ActiveSupport::Notifications, which means you can subscribe to cacheread.activesupport, cachewrite.activesupport, cachefetchhit.activesupport, and cachedelete.active_support events and forward them to your metrics platform. This is the cleanest way to get per-key visibility without instrumenting every call site. A typical subscriber records the key, the duration, and whether the read was a hit, then aggregates into histograms and counters that your dashboards can query.
# config/initializers/cache_instrumentation.rb
ActiveSupport::Notifications.subscribe('cache_read.active_support') do |name, start, finish, id, payload|
  duration = (finish - start) * 1000.0
  key = payload[:key]
  hit = payload[:hit]

  StatsD.increment('rails.cache.read', tags: ["hit:#{hit}"])
  StatsD.histogram('rails.cache.read.duration_ms', duration, tags: ["key:#{key}"])
end
Beyond hit rate, you should track latency percentiles for cache reads and writes. A p99 read latency that climbs from one millisecond to fifty milliseconds usually means the store is under memory pressure and evicting aggressively, or that the network path to the store is degraded. Tracking latency alongside hit rate lets you distinguish between a cache that is missing and a cache that is slow — two problems with very different fixes. A slow cache is often worse than no cache, because it adds latency without providing the expected benefit.
Cache size and eviction rate are the other critical metrics. If your store is evicting entries faster than you are writing them, your effective cache is much smaller than its configured size, and your hit rate will suffer. Monitoring eviction rate, memory usage, and the ratio of writes to evictions tells you whether you need to increase capacity, shorten TTLs, or reduce the number of distinct keys. On Redis, the INFO stats command exposes evictedkeys and keyspacehits, which are the raw inputs for these calculations.
Finally, instrument invalidation. Every time you delete a cache key or bump a version, record it. A sudden spike in invalidations often precedes a performance incident, because it means the cache is being cleared faster than it can be repopulated. Correlating invalidation spikes with deployment events, data migrations, or batch jobs is one of the fastest ways to diagnose a cache that has stopped helping. Observability is not optional for a production caching layer; it is the difference between a cache you understand and a cache you hope works.
Common Pitfalls, Anti-Patterns, and When Not to Cache
Caching is a powerful tool, but it is also one of the easiest ways to introduce subtle, hard-to-reproduce bugs. The most common pitfall is caching personalised content under a non-personalised key. If a fragment varies by user, role, locale, or feature flag, that variation must be part of the key. Auditing every cache call for hidden dependencies is tedious but essential, and it is far cheaper than debugging a bug where users occasionally see each other’s data.
A second pitfall is caching data that changes frequently. If a value changes on every request, caching it adds overhead without benefit: you pay for a write and a read on every request, and you get a miss every time. The rule of thumb is that caching pays off when the read-to-write ratio is high — roughly ten reads per write or more. Below that ratio, the cache is more likely to hurt than help, and you should optimise the underlying computation instead.
A third pitfall is ignoring cache invalidation on write paths that bypass Active Record. Bulk updates via update_all, direct SQL, background jobs that write to the database without touching timestamps, and external systems that modify shared data all bypass the timestamp mechanism that Rails relies on. If any of these exist in your application, you need explicit invalidation logic — a version bump, a key deletion, or a touch call — to keep the cache consistent. Documenting these write paths is part of designing a correct caching layer.
There are also cases where caching is simply the wrong answer. If your bottleneck is a slow external API, caching the response helps, but so does adding a timeout, a circuit breaker, and a fallback. If your bottleneck is a slow query, caching hides the problem but does not fix it; adding an index or rewriting the query is usually better. If your bottleneck is CPU-bound rendering, caching helps, but so does reducing the amount of work in the view. Caching should be the last optimisation you reach for, not the first, because it adds complexity and failure modes that simpler fixes avoid.
Finally, beware of caching as a substitute for understanding your workload. A cache that is added without profiling often caches the wrong things: the cheap computations that were never the bottleneck, while the expensive ones remain uncached. Profile first, identify the hot paths, and cache deliberately. The engineers who get the most from Rails caching are the ones who measure before they optimise, and who treat every cache call as a correctness decision rather than a performance trick. Done well, caching is invisible — users simply experience a fast application. Done poorly, it is a source of bugs that erode trust in the entire system.
